
HTML Annotation
Label visible text, entity relationships, and properties in saved HTML pages while preserving rendered context.
HTML annotation turns saved web pages into structured training and evaluation data. Work with the rendered page, select visible text, and add ontology-defined labels while keeping headings, images, tables, and nearby content available as context.
See HTML annotation in action
The demo shows the rendered HTML work surface and text annotations in their original page layout.
Before you begin
Prepare saved
.htmlor.htmfiles. Check that the content needed for annotation is visible in the saved source.Upload the files and wait for processing to finish before attaching or publishing them as dataset members.
Configure entity classes, class properties, Item Properties, and allowed relations in the project ontology.
Write instructions for span boundaries, repeated text, navigation content, missing fields, and ambiguous values.
Open an assigned item from the project data view or Task Queue.
See Annotation Workbench for shared navigation, saving, history, comments, and stage actions.
Understand the HTML work surface
The viewer displays a prepared snapshot of the uploaded page. Select text in the rendered content rather than editing HTML source code. Fixed-width, fit, and responsive viewing options change the presentation of the same snapshot; they do not create a new source revision.
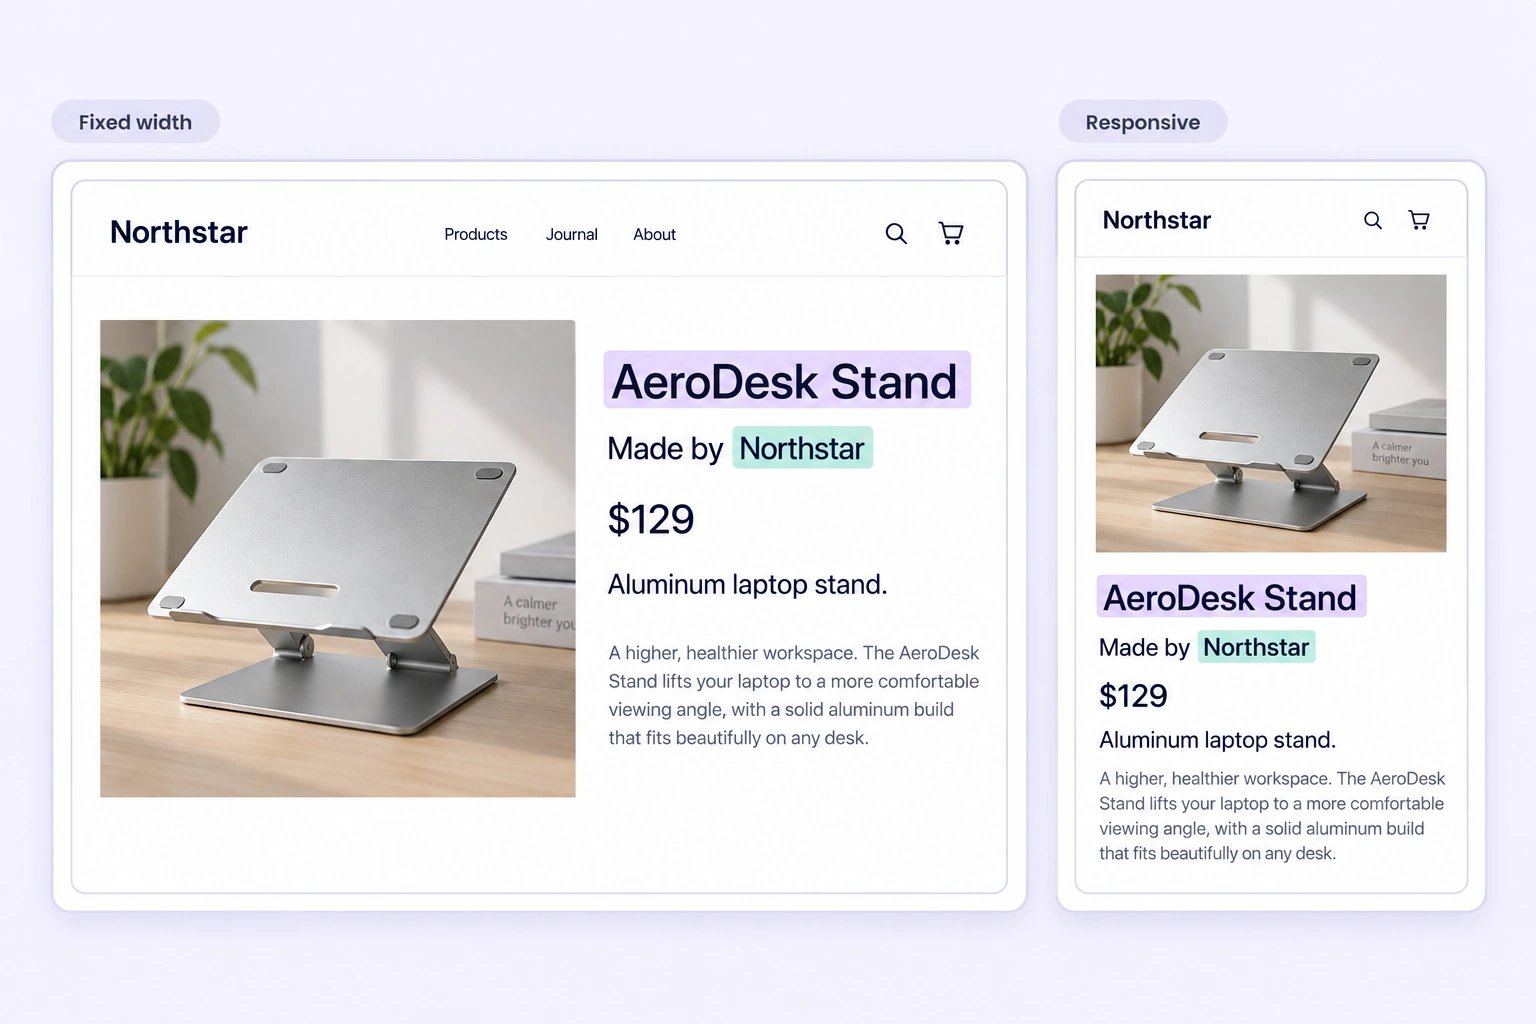
Inspect the same saved page at a useful width while retaining its annotation context.
Images, charts, and controls in the page provide context. They do not become separate image or video annotation surfaces within the HTML item. Prepare another source item when the task requires labeling that media directly.
Supported annotation model
Text span
A contiguous range of visible text and its class.
Product name, price, employer, or publication date.
Class properties
Structured values attached to an entity.
Currency, employment type, or a manually entered normalized value.
Item Properties
Values describing the complete saved page.
Page type, language, relevance, or source category.
Relation
An ontology-defined connection between entities in the same page.
Product made_by Brand or Job offered_by Employer.
Text selections may cross adjacent text nodes, but must remain contiguous and non-overlapping. Use Item Properties for whole-page classification so it does not overlap entity spans. Relations and properties add meaning to entities; they are not additional drawing tools.
Label visible text precisely
Select the exact text required by the instructions and apply its class. Check whether punctuation, currency symbols, units, or qualifiers belong in the span. A page may repeat the same value in a heading, summary, and recommendation; annotate the occurrence that belongs to the target record.
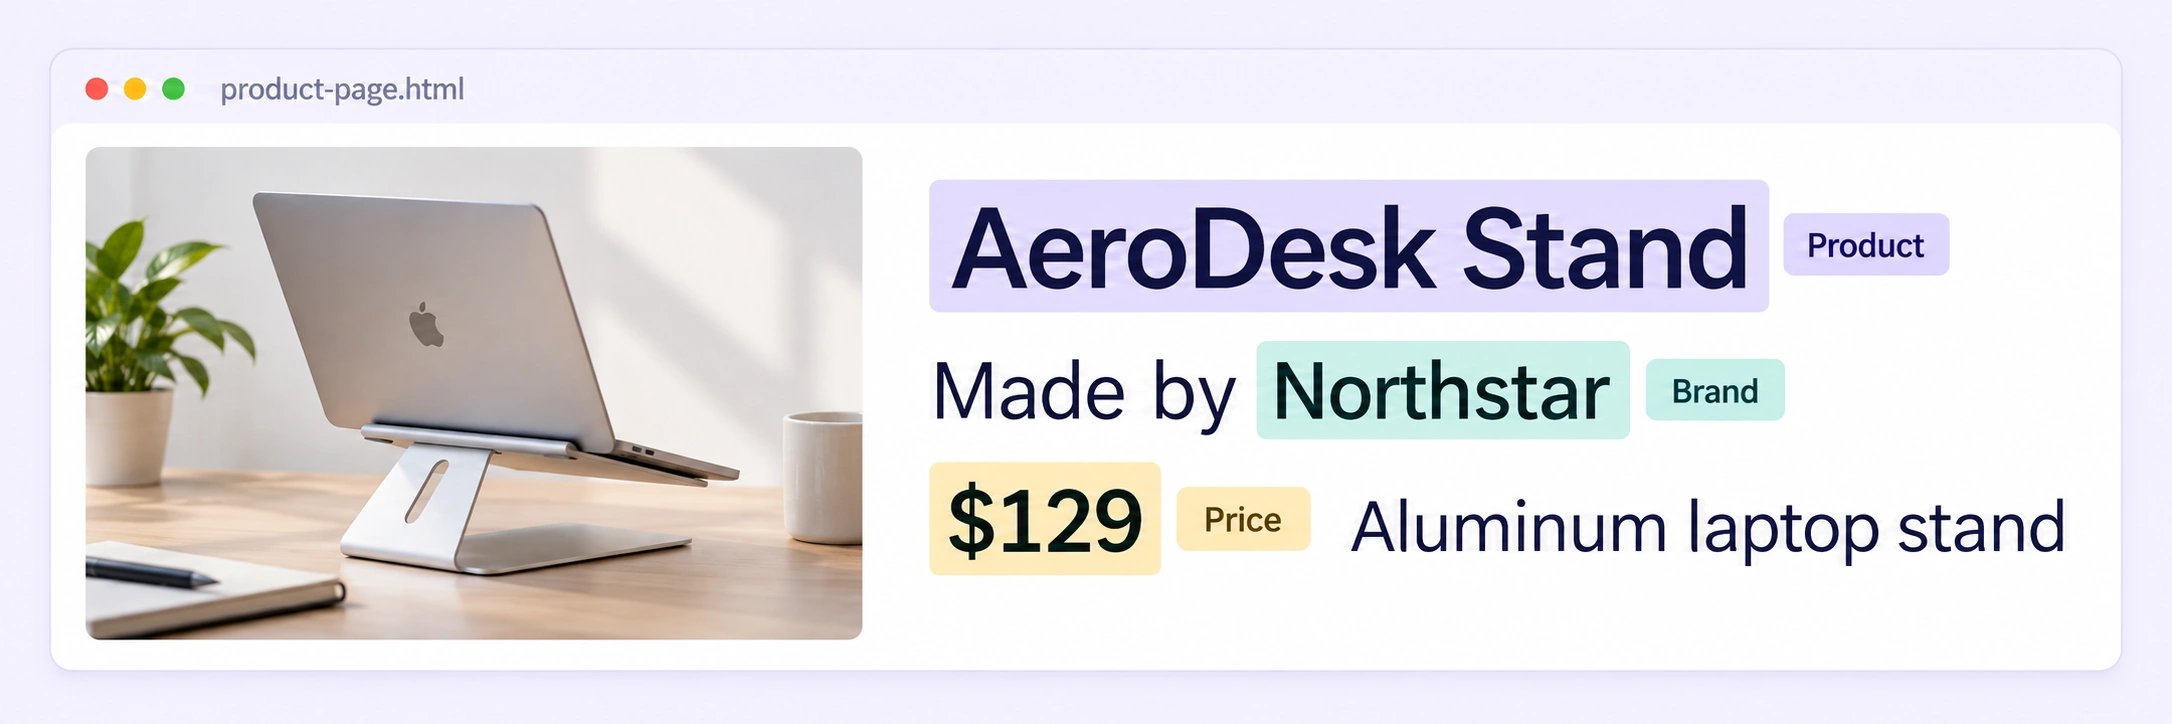
Product, Brand, and Price spans remain grounded in the rendered product page.
For example, a price policy might require $129, including the currency symbol. Apply that rule consistently rather than alternating between $129 and 129. Store a normalized amount in a configured property if the task requires it; normalization is an annotation decision.
Connect entities and complete properties
Choose relations allowed by the ontology and verify their direction and endpoints. Connect the product to its own brand or price, especially when several products appear on the page. Use class properties for entity details and Item Properties for page-level context.
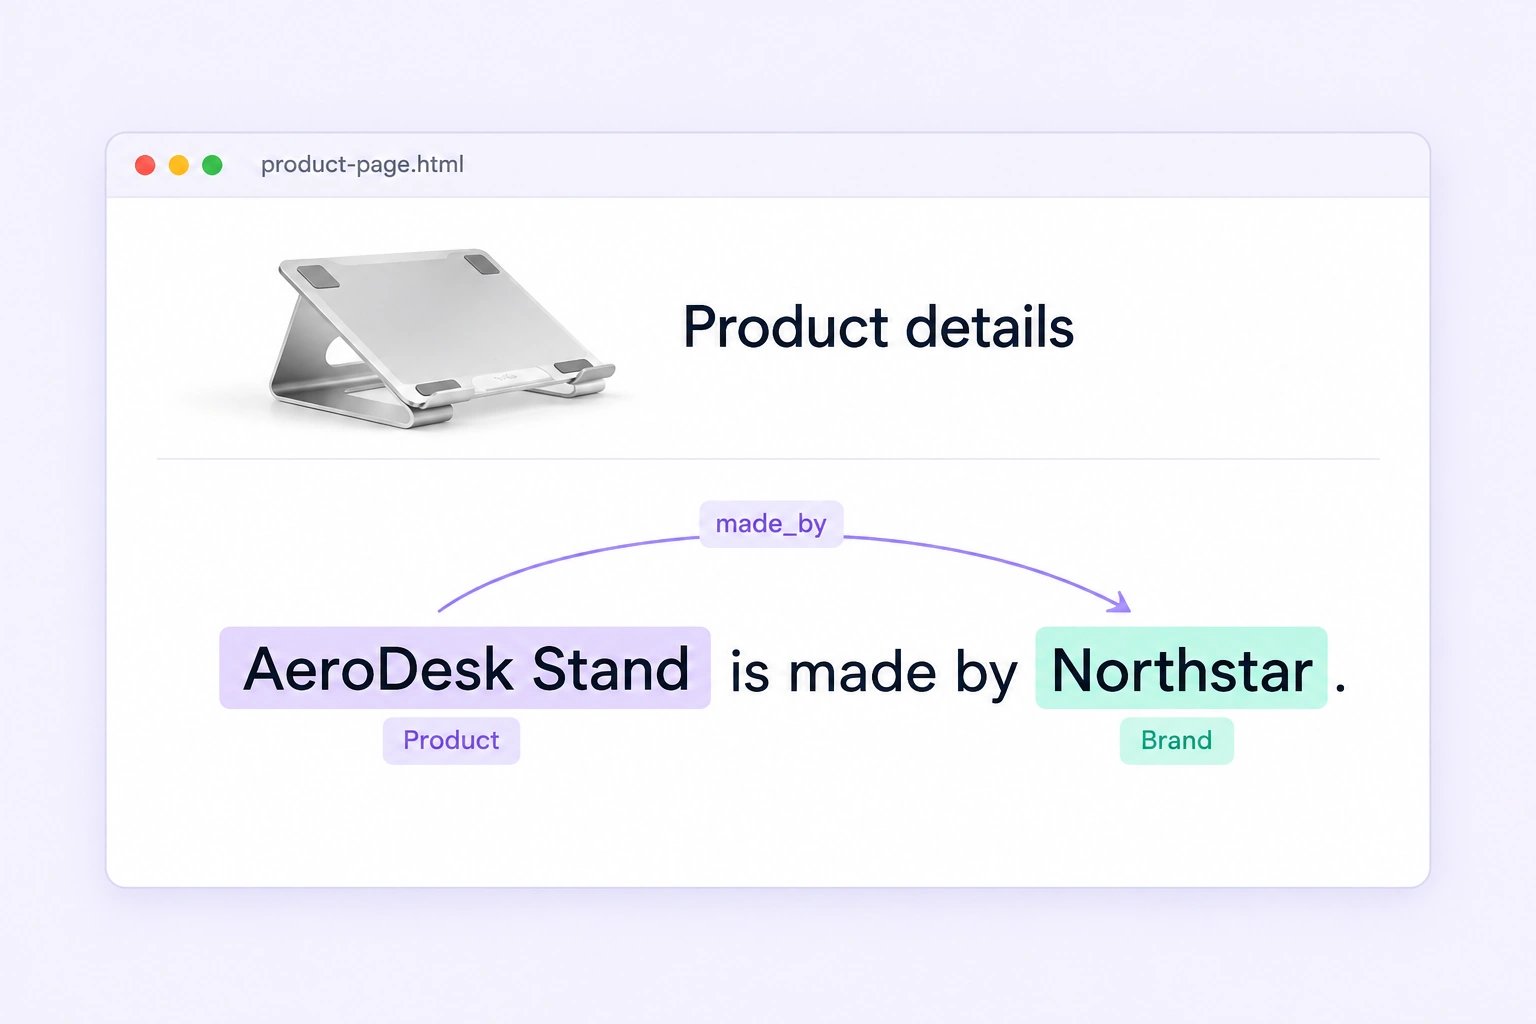
A same-page relation connects the product entity to its brand.
Annotate one production item
Inspect the source. Confirm the page identity and that the relevant content survived saving and processing.
Locate the target content. Distinguish the main record from navigation, advertisements, and related items using the task instructions.
Create spans. Label complete, contiguous text without overlapping another entity.
Add structure. Complete properties, classify the page, and create the required relations.
Review in context. Check repeated values, missing fields, relation direction, and span boundaries at a readable width.
Save and submit. Resolve applicable findings, save the annotation, and use the available workflow action to hand it to the next stage.
Quality review
Source identity
Labels refer to the intended saved page, not a later website revision.
Span boundaries
Complete words and task-required symbols are included without unrelated text.
Coverage
Required fields are labeled, or absence is handled according to instructions.
Relationships
Endpoints belong to the same target and the relation direction is correct.
Properties
Entity and page values are complete and use the intended ontology choices.
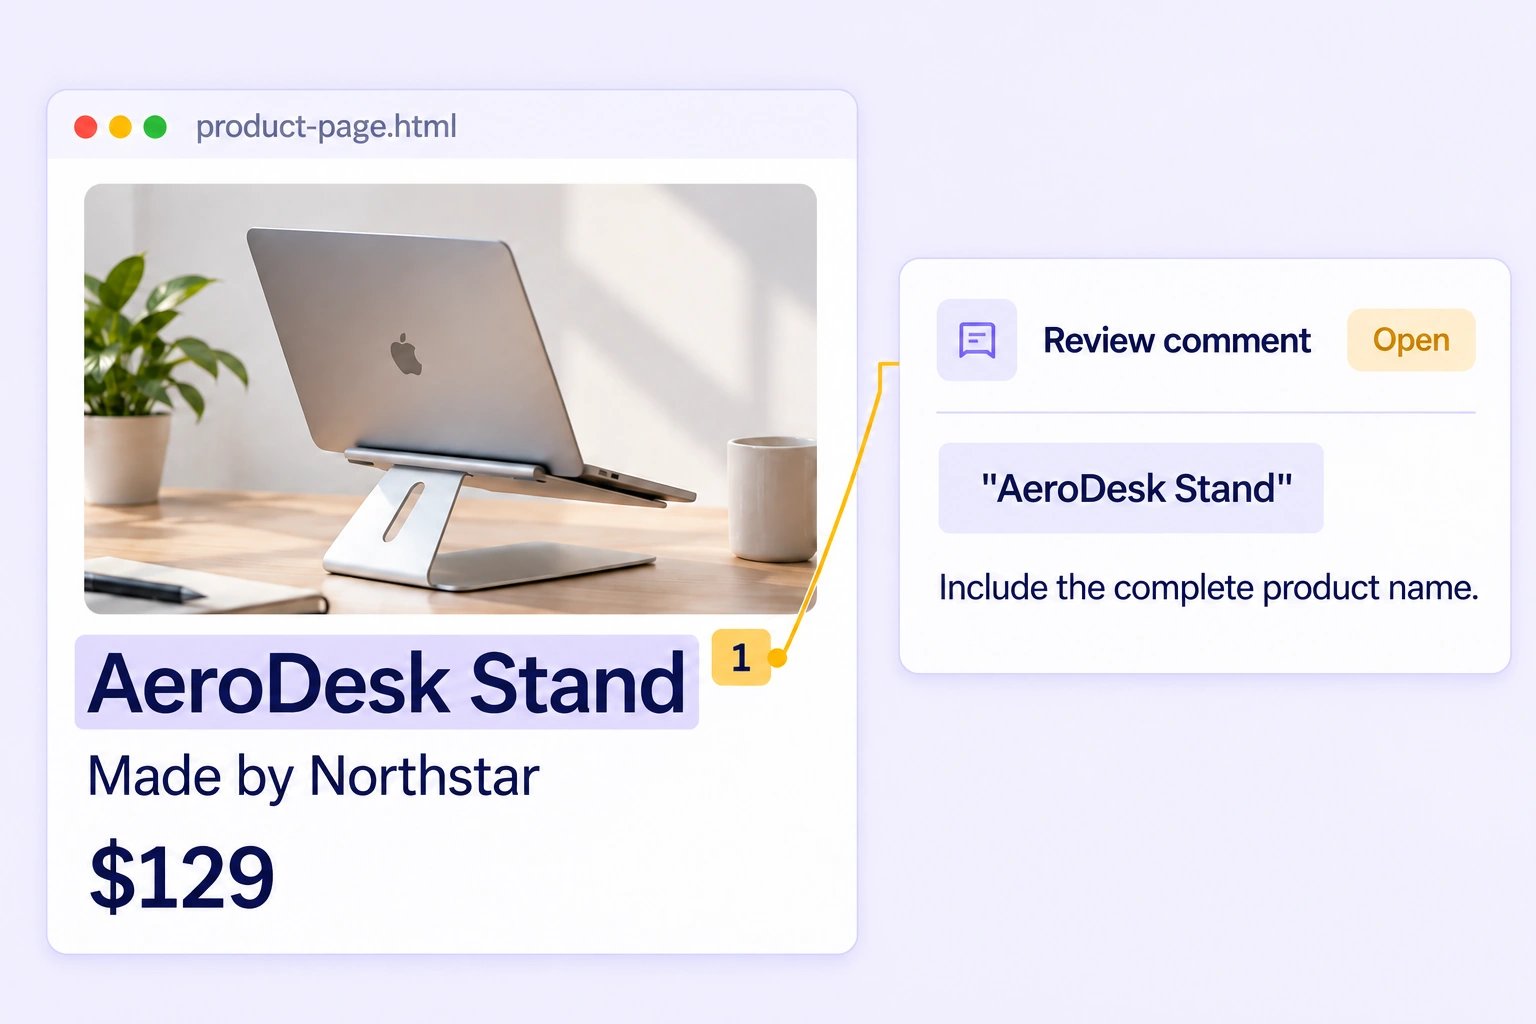
Anchor feedback to the text that needs correction so another annotator can resolve it in context.
Use Review Stages for expert decisions, Consensus to compare independent annotations, and Quality Gate for comparisons with approved answer keys. Agreement is evidence of consistency, not a guarantee that the extraction policy is correct.
Prepare a traceable release
Use folders, tags, filenames, and available metadata to curate the source pages. A dataset version fixes the selected source membership. After annotation and review, create a project annotation release to freeze the labels for delivery.
HTML JSONL and native UUEF exports preserve text, entity properties, relationships, page properties, and snapshot or anchor identity. Verify representative exported spans against the saved page and check that the downstream consumer handles the source identity correctly. An export source URL can identify Unitlab's release source rather than the original website.
Troubleshooting and boundaries
Required text is missing
Inspect the saved file and processing state. Prepare a complete source before annotation.
A selection overlaps another entity
Adjust the boundary or express the additional meaning as a property or relation.
The original website changed
Treat the revised page as a new source; changing the viewer width does not re-anchor labels to it.
A field has several plausible values
Leave contextual feedback and route it to the assigned reviewer.
This workflow annotates saved pages. It does not provide website crawling, raw DOM or HTML-attribute labeling, or browser interaction recording.
Next steps
Define acceptance rules in Project Instructions.
Connect annotation and review with QA Workflows.
Prepare delivery using Create a release.
Explore the Unitlab HTML Annotation overview.