
LiDAR Annotation
Prepare LiDAR point clouds, ZIP scenes, and calibrated cameras, then annotate 3D objects, point labels, and tracks with review and export workflows.
Open the LiDAR annotation demo in a new tab.
LiDAR annotation turns 3D point clouds into labeled objects, spatial regions, point-level segments, and temporal tracks. Unitlab combines a native 3D editor with calibrated camera context, shared ontologies, camera-assisted automation, and annotation quality assurance.
Before you begin
Prepare a representative scene and confirm its coordinate system, dimensions, sensor calibration, and frame order using the examples below.
Create or select a project, make the required ontology Live, and define object classes, 3D geometry, properties, and scene-level Item Properties.
Write Project Instructions covering object extent, occlusion, sparse returns, track identity, and the first and last valid frame.
Configure the workflow and review route before starting a large batch.
See Data upload for destinations and processing status, and Annotation Workbench for shared navigation, saving, comments, and workflow actions.
Prepare LiDAR data
A LiDAR scene is one annotation item containing a single point cloud or a sequence of frames. Each frame can contain clouds from several LiDAR or radar sensors and images from several cameras.
Use a single cloud file for a one-frame scene, a ZIP for one complete scene, or select a folder to upload one or more recordings. Add a scene.json file when you need explicit frame pairing, camera calibration, sensor mounting, or vehicle poses.
Choose an upload layout
One point cloud
Upload one .pcd, .ply, or .bin file.
A sequence from one sensor
Put the frame files in one folder and select that folder, or ZIP the scene.
LiDAR with camera images
Use a folder per sensor and a scene.json containing calibration.
Several point sensors with different mountings
Use the multi-sensor scene.json structure below.
Several recordings
Keep each recording in its own scene folder and select their parent folder. Review the detected scenes before uploading.
A nuScenes dataset
Select the extracted dataset folder with its tables and samples directory. See the nuScenes instructions below.
For a basic sequence, use matching filename stems across the sensor folders:
Without scene.json, files with the same stem belong to the same frame. For example, 000001.pcd matches 000001.jpg; it does not match frame_000001.jpg. Use one unique stem per frame within each sensor folder. Zero-padding is recommended for readable sequences, but consecutive numbers are not required.
The first point-cloud folder in natural filename order defines the frame list. Other sensors and cameras contribute their matching files when present. A file found only in a secondary sensor folder does not create an extra frame. To control the order and pairing explicitly, list the files in scene.json.
Camera images in an uncalibrated folder layout can be viewed as references. Projecting 3D annotations onto those images requires camera intrinsics and a camera pose. Multiple clouds uploaded without mounting information are treated as already sharing one coordinate frame.
One data subfolder inside each sensor folder is also supported:
This recognizes the folder structure. Calibration files from another format, such as KITTI calib.txt, still need to be converted into the scene.json fields described below.
For several recordings, keep clear scene boundaries:
Select the parent folder and review 3D scenes found. Each selected scene becomes one item. If separate recordings have the same frame names, the uploader may initially interpret their folders as sensors of one scene. Use They are N separate scenes when that is the correct interpretation. Check any warnings about unused camera folders or missing files before selecting Upload N scenes.
Prepare the point-cloud files
Use metre units and a Z-up scene coordinate system. Keep each sensor's points in its own local coordinates when scene.json supplies its mounting transform. Do not transform the points into the vehicle frame and also apply the original mounting transform.
PCD
PCD supports ascii, binary, and binary_compressed data. Every file must declare x, y, and z fields. Intensity is optional. This three-point ASCII example is a complete .pcd file:
For binary PCD, the body must agree with the header's field types, sizes, counts, and point count. Use a standard PCD writer for binary_compressed; it uses the PCD LZF layout rather than ZIP compression. A VIEWPOINT header is not a substitute for the mounting poses in scene.json.
PLY
PLY supports ASCII, binary little-endian, and binary big-endian encodings. Its vertex element must contain scalar x, y, and z properties. This is a complete three-point ASCII example:
Only the vertex positions and optional intensity are used for the point cloud. Mesh faces, colors, and normals do not become annotation geometry. Keep the vertex properties scalar; list properties on the vertices or on an element before the vertices are unsupported.
BIN
BIN files have no header. Use little-endian 32-bit floating-point values, normally four values per point:
A four-column file therefore contains 16 bytes per point. A file with five columns, such as x, y, z, intensity, ring, contains 20 bytes per point. Declare a nonstandard layout under that sensor in scene.json:
bin_fields lists the columns in their stored order. It accepts 3 to 16 distinct lower-case names and must include x, y, and z. All values still use float32. Extra columns are read as part of each record but are not separately annotated. Layout detection can recognize some undeclared files, but an explicit declaration avoids an ambiguous guess.
Across the three formats, missing intensity becomes zero. Points with invalid x, y, or z coordinates are removed. An empty sensor sweep can be omitted from a frame, but every frame needs valid points from at least one sensor.
Add camera images and calibration
Camera images must be JPEG or PNG. Keep one image resolution per camera, and use intrinsics calibrated for that exact image size and preprocessing. If you resize or crop the images, adjust the intrinsics before uploading.
Place calibration inside a UTF-8 file named exactly scene.json at the scene root. Separate files named intrinsics.json or extrinsics.json are not read automatically.
For one LiDAR and one camera, the folder can look like this:
The following is a complete two-frame manifest. Its numbers are illustrative; replace them with your own calibration.
Download the simple calibrated scene to inspect or upload this structure. It contains two frames, six synthetic points in total, and plain placeholder camera images. Its README explains what to replace for real data.
Intrinsic matrix
intrinsics is a nested 3×3 matrix, normally [[fx, skew, cx], [0, fy, cy], [0, 0, 1]]. The focal lengths fx and fy must be positive. The principal point cx, cy is measured in image pixels. Supply numeric values, not strings or a flattened array.
Camera pose and axes
In this simple structure, extrinsics describes the camera's pose in the LiDAR frame. position is the camera origin in metres; rotation is a unit quaternion with named qx, qy, qz, and qw components. translation can be used instead of position, with the same x/y/z object.
The transform maps a point from camera coordinates into LiDAR coordinates:
If your existing calibration maps LiDAR points into the camera, invert it first. For point_camera = R × point_lidar + t, the inverse uses Rᵀ and -Rᵀ × t. Convert the inverse rotation to the named quaternion fields. A 4×4 matrix, Euler-angle object, or quaternion array cannot be pasted into extrinsics directly.
convention controls the camera axes:
opencv
X right, Y down, Z forward. This is the default.
opengl
X right, Y up, Z backward.
Both intrinsics and the camera pose are needed for calibrated projection. Check the projected point cloud and cuboids against the camera image before relying on camera-assisted annotation or tracking.
Lens distortion
Omit distortion for the default pinhole model, or specify an exact model and named coefficients:
pinhole
None
radial
k1, k2, k3
brown-conrady
k1, k2, k3, p1, p2
rational-polynomial
k1, k2, k3, k4, k5, k6, p1, p2
fisheye
k1, k2, k3, k4
division
k
ucm
xi, k1, k2
cylindrical
None
Missing coefficients are zero. Use calibration for the images you upload. For images already rectified to a pinhole camera, use the rectified intrinsics and avoid applying the original lens distortion a second time.
Prepare multiple sensors and vehicle poses
Use frames_of_reference when several sensors need separate mounting transforms. Each sensor has a node with the same name as its entry in sensors. Its pose describes that sensor in its named parent frame.
In this example, ego is the vehicle. Sensor mountings stay fixed, while frames[].poses.ego gives the vehicle's position and orientation for each frame. Keep the raw points in each sensor's local coordinate system.
Download the multi-sensor scene. It contains two frames, two LiDAR sensors with three synthetic points per cloud, and one camera. Its calibration and vehicle movement are illustrative and must be replaced with real measurements.
Use these rules when adapting the example:
Give every sensor a unique name containing only letters, digits,
_, or-, up to 64 characters. Reserveworldfor the root coordinate frame.Declare a sensor as
lidar,radar, orcamera.reference_sensormust name a LiDAR or radar sensor.Supply a fixed pose for every sensor mounting. Intermediate rigid mounting frames are allowed, but the parent chain must lead to
worldwithout loops.Each frame needs at least one point-cloud file under
clouds. A sensor or camera can be absent on individual frames. Use only paths that exist in the scene.Supply the vehicle pose for every frame when you need world-aligned annotations. A fixed pose on the vehicle node can provide the default for a static rig.
Put camera mounting poses in
frames_of_reference, rather than the simple form'sextrinsicsfield.
If a camera exposure needs a different pose from the LiDAR sample, a frame may also include poses.cam_front. That pose replaces the camera's mounting for that frame and is still relative to its named parent. Per-frame movement is supported for the vehicle and cameras that have no child reference frames; point-sensor mounting poses remain fixed.
Set frame timing and ground height
The order of the frames array is the playback order. Explicit manifests can pair differently named cloud and image files; they do not require matching stems.
timestamp_ns is optional. If used, supply it on every frame as a nonnegative JSON integer in nanoseconds, with strictly increasing values. For example, 0 and 100000000 are 0.1 seconds apart. Do not quote the numbers or write seconds in this field. Preserve integer precision when generating epoch timestamps.
Raw sensor samples are not grouped automatically by time tolerance. Pair the desired samples into frames before upload. samples and sync_tolerance_ms are not supported alternatives to frames.
Optional ground_z states the ground height in metres in the reference point sensor's local coordinates. It can apply to the whole scene or be overridden on a frame. If it is omitted, Unitlab estimates a ground height from nearby points. This is one height for the frame, so inspect placement on sloped or uneven surfaces.
Upload a nuScenes dataset folder
Extract the dataset and preserve the relationship between the sample files and the versioned JSON tables:
Select the nuscenes folder in the web uploader. Unitlab reads the six tables, identifies the recordings, and generates each scene's calibration and frame mapping. Review the scenes and any missing-file notices, then choose the recordings to upload.
This import uses key frames only. Intermediate sweeps are not uploaded. The camera intrinsics, sensor mounting, vehicle poses, and available camera-specific poses are carried into the generated scene description. The reference LiDAR supplies frame timing. Upload the extracted folder for this conversion; a ZIP containing an entire nuScenes dataset is not automatically split and converted in the same way.
Package, upload, and check readiness
For ZIP uploads, package one scene using standard Deflate compression or no compression. Place scene.json and the sensor folders directly in the archive, or inside one enclosing scene folder. Avoid additional wrappers that hide the manifest below another directory. Use forward-slash relative paths and do not include encrypted files or symbolic links.
The current default preparation limits are listed below. Deployment settings and workspace allowances may impose different limits.
Uploaded scene size
20 GiB
Frames in one scene
1,000
Files in one scene
100,000
Unpacked ZIP content
40 GiB
Point sensors and cameras
16 of each
Points in one cloud file
5 million
Total retained points in one scene
1 billion
One source cloud file
2 GiB; ASCII sources have a 1 GiB limit
Declared decoded ASCII or compressed point table
512 MiB
Scene manifest
16 MiB
Camera image
50 MiB and 16,384 pixels per side
Your workspace's data allowance also applies, with one data unit per frame. Once transfer finishes, wait for scene preparation to complete before opening the annotation editor. If preparation fails, use the reported filename and error to fix the source rather than changing unrelated files.
Before annotating a large sequence, check a few frames. Confirm that sensor clouds align, camera projections land on the correct objects, frame order is correct, and image sizes remain consistent. Camera-assisted tracking needs a calibrated camera with continuous images over the frames you intend to track.
Troubleshoot scene preparation
Point-cloud format is not recognized
Use PCD, PLY, or BIN. Convert LAS, LAZ, or E57 into a supported point-cloud representation before upload.
BIN points look scattered or misaligned
Confirm little-endian float32 values, metres, and the exact bin_fields column order. Check that mounting transforms are applied only once.
Cameras are visible but projection or automation is unavailable
Add the camera's intrinsics and pose in scene.json, and provide its matching image for the current frame.
Projected objects are shifted or behind the camera
Verify camera-to-LiDAR transform direction, quaternion components, camera convention, image resolution, and frame pairing.
Frames or sensors are missing
Check filename stems in automatic layouts, explicit manifest paths, and the uploader's scene-versus-sensor grouping.
Scene preparation rejects the ZIP
Check the manifest location, relative paths, archive contents, file encodings, and the reported size or point-count limit.
Understand the LiDAR work surface
The LiDAR Workbench brings together the 3D point cloud, object list, ontology controls, frame timeline, and sensor views. Start in the perspective view to understand the scene. Use top, side, and rear orthographic views to check a selected cuboid's dimensions and position. Calibrated camera panels add appearance and visibility evidence that may be hard to resolve from sparse points alone.
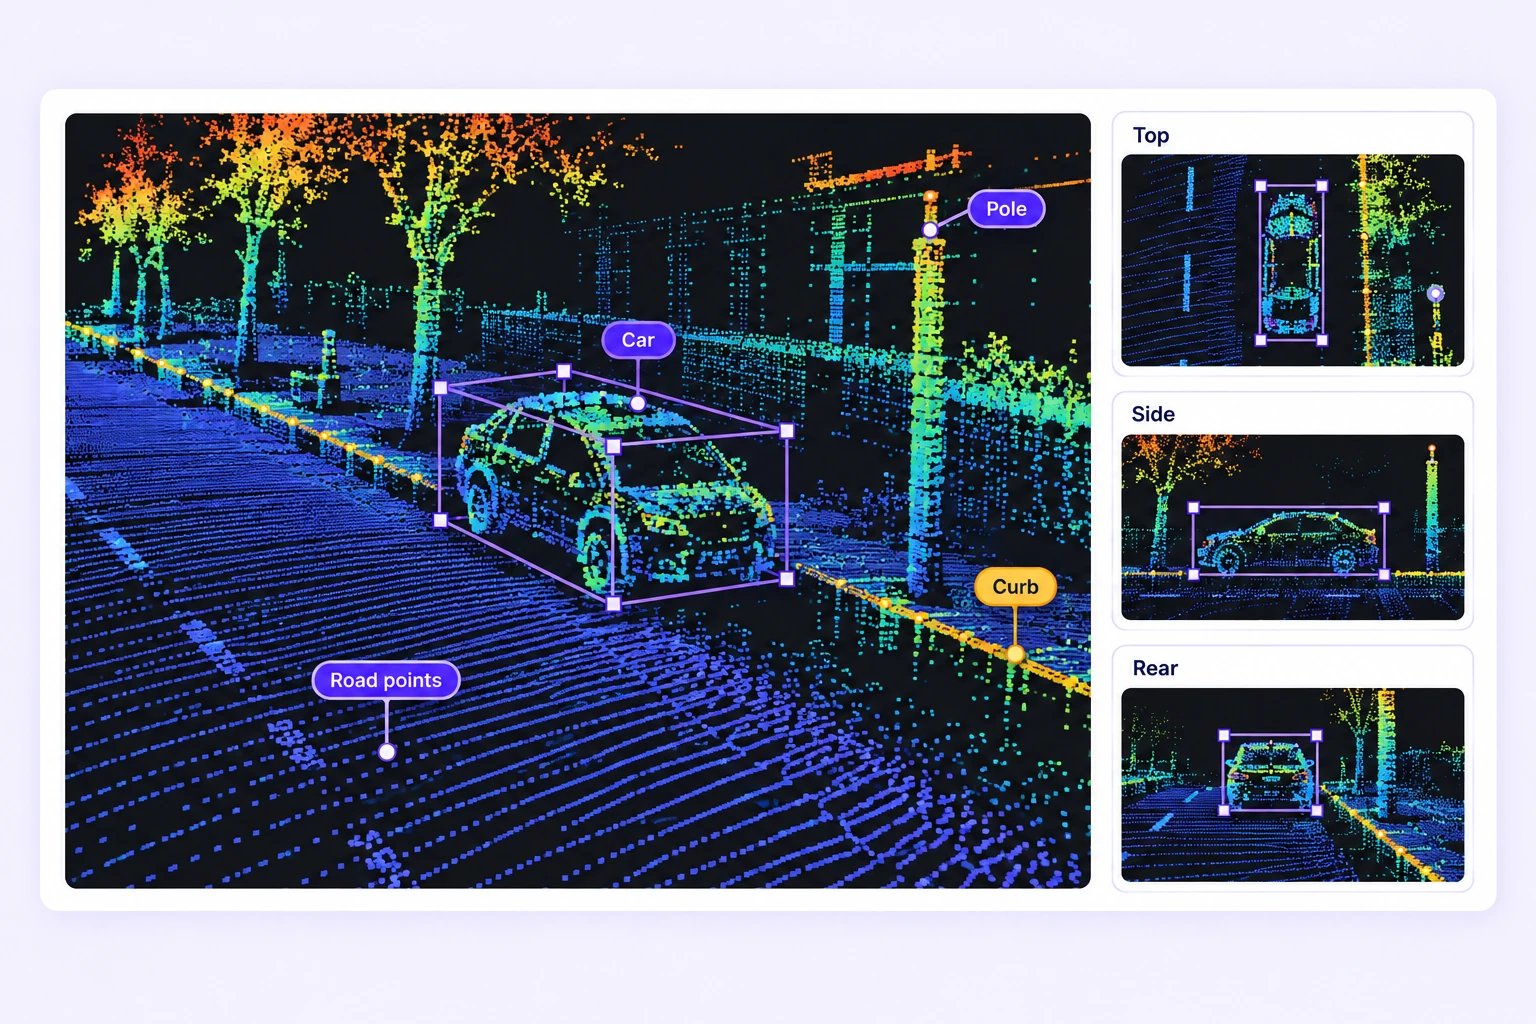
Perspective and orthographic views help you inspect the same 3D geometry from complementary directions. This illustration summarizes the tools; use the demo above to see the product interface.
Inspect point color and visibility settings before drawing. Hide distracting geometry when needed, then restore scene context for review. A box that looks correct from one viewpoint may still include the road, overlap another object, or have the wrong height.
Supported annotation model
3D cuboid
Oriented object extent for cars, pedestrians, equipment, and other objects.
Center, length, width, height, and rotation in several views.
Point segmentation
Semantic class labels and separate object instances on individual points.
Missed points, background leakage, and separation between adjacent instances.
3D polygon
Closed spatial regions described by vertices.
Boundary placement and vertex order.
3D polyline
Open boundaries such as curbs, barriers, and corridors.
Continuity and alignment with the point cloud.
3D point
A spatial landmark or precise location.
Position in all three dimensions.
3D sphere
A volumetric region described by a center and radius.
Center, radius, and intended coverage.
Linked camera box
A 2D camera box associated with a 3D cuboid.
The object, sensor, frame, and 3D association.
Object properties and Item Properties
Structured facts about an object or the whole scene.
Required values, conditional fields, and frame-varying state.
Tracks, visibility ranges, and keyframes
Object identity and geometry through a sequence.
Continuity, entrances and exits, manual corrections, and temporal boundaries.
Choose the type in the ontology before labeling. A cuboid drawn on a 2D image and a LiDAR 3D cuboid represent different geometry; use the native LiDAR editor for point-cloud coordinates.
Calibrated camera views and sensor fusion
A LiDAR scene can combine multiple LiDAR or radar point-cloud sensors with camera images. The scene manifest defines which files belong to a frame and how the sensors relate spatially. Projection uses the supplied camera intrinsics, convention, distortion model, and sensor poses.
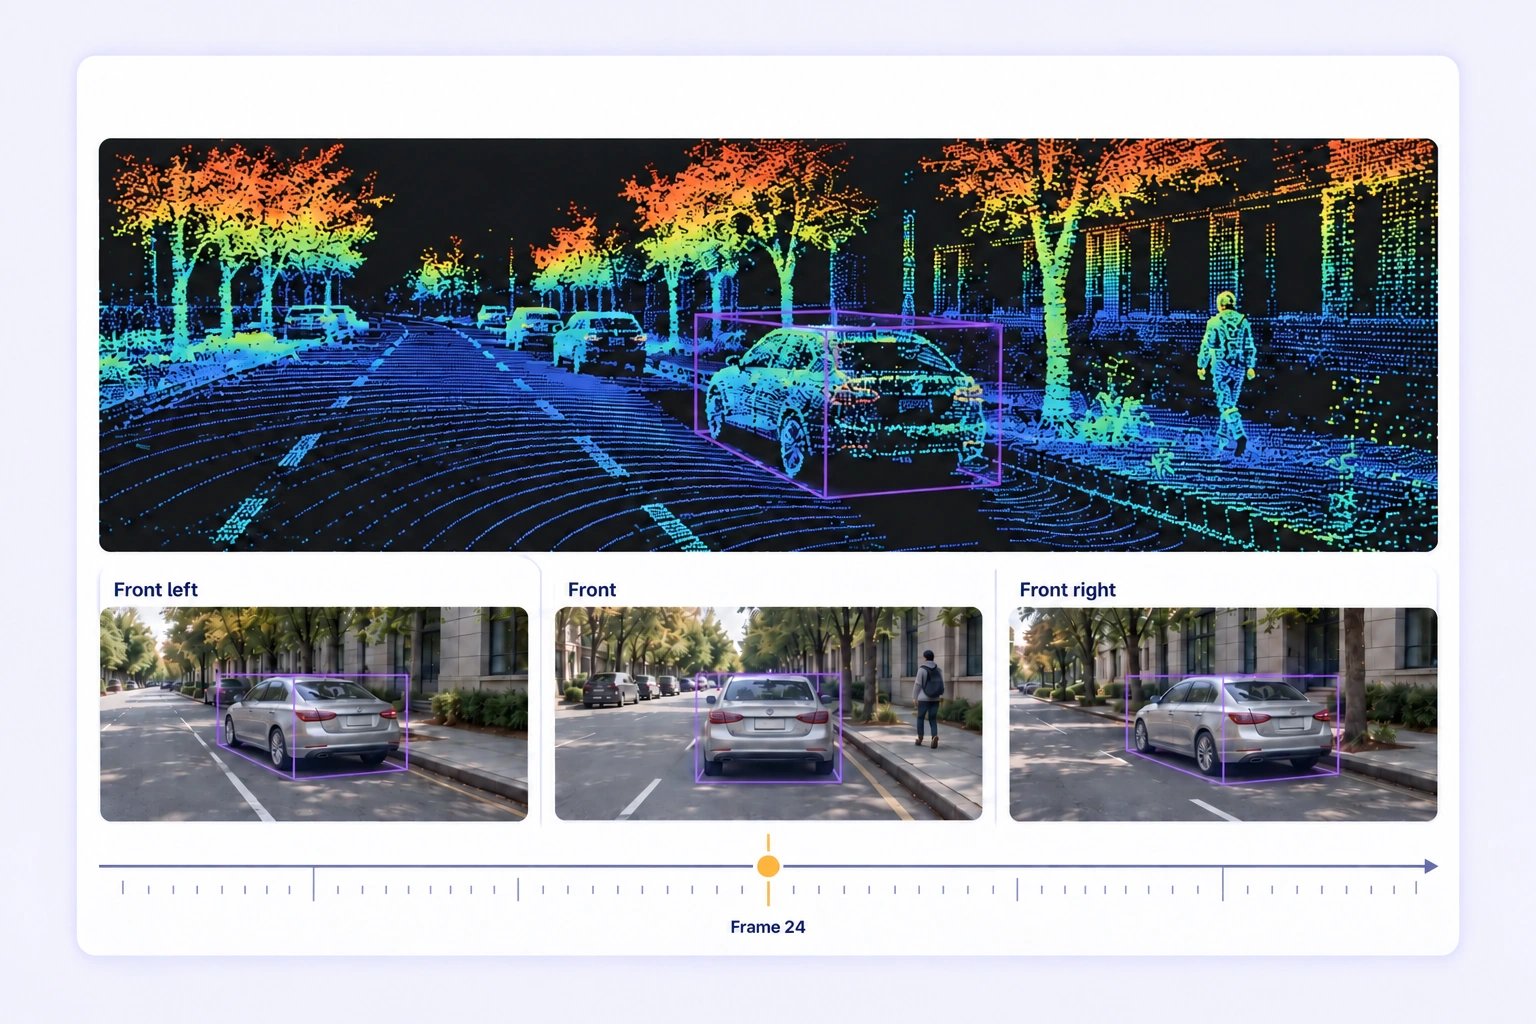
Use camera appearance to confirm object identity and point-cloud geometry to check 3D extent. Calibrated projection depends on the scene's actual sensor calibration.
Check one clearly visible object before annotating the full scene. Its projected geometry should align with the same object in the correct camera image and frame. Consistent offset, mirroring, incorrect scale, or a box behind the camera usually points to calibration, coordinate conventions, or frame pairing that needs correction.
A folder containing camera images provides context, but images alone do not supply calibration. See the manifest examples above before enabling camera-assisted workflows. A calibrated sensor scene also differs from a generic Data Group: grouping files does not calculate sensor transforms or synchronize unrelated recordings.
Link a camera box to a 3D cuboid
Select the 3D cuboid, then click the desired camera's name or image in the camera row. Open View Settings → Camera Image and, under 2D box, click Link 2D box. The camera must have calibration and see the cuboid on the current frame. Unitlab creates a linked 2D box from the cuboid's projection; adjust the box on the camera image to match the visible object. Use Remove 2D box in the same section to delete it.
The linked box belongs to that cuboid and camera, follows the cuboid's class, and is removed when the parent cuboid is deleted. A manual 2D box edit does not reshape the 3D cuboid. Review both geometries when making corrections.
Annotate one production scene
2. Create the first reliable annotation
Choose the class and annotation tool. For a cuboid, start where the object has clear point returns, then adjust its extent and orientation in perspective and orthographic views. For point segmentation, label only the intended points and inspect the boundary from another angle.
Find Similar, Auto-Tracking, and interpolation
LiDAR camera-assisted automation uses calibrated camera evidence together with point-cloud geometry. Find Similar starts from a selected 3D cuboid. Unitlab automatically chooses a calibrated camera that sees it, finds candidate objects in that camera's current-frame image, and fits editable 3D cuboids to supporting LiDAR points. Auto-Tracking follows camera evidence across frames and produces editable 3D keyframes. The input must contain the relevant point clouds, matching images, and usable calibration.
Interpolation fills supported geometry between explicit keyframes. It is useful when you can define reliable endpoints, but it does not establish object identity or prove that the object follows a straight, unobstructed path. Review intermediate frames, occlusion, turns, changes in visibility, and sparse returns.
Use Batch View to compare a cuboid across frames and find size, orientation, or position drift. Preserve deliberate manual corrections and inspect the resulting track after every automated pass. Generic Find Similar explains reference-driven assistance; the LiDAR workflow here requires calibrated camera and point-cloud context.
Find similar cuboids on the current frame
Open a frame that has usable point clouds and a matching calibrated camera image. Create or select a reliable 3D cuboid around the reference object.
Click Find similar in the top header. Unitlab chooses a calibrated camera that sees the selected cuboid and has an image for this frame. The camera currently shown in the 3D view does not determine the search camera.
Review the proposed cuboids in the 3D view and camera images. Adjust the confidence threshold to filter the candidates. The proposals are not saved as annotations until you approve them.
When the search finishes, click Track all in a multi-frame scene, or Accept all in a single-frame scene. Accepted cuboids use the reference object's class. Clear discards the proposals.
Check the accepted cuboids and their temporal ranges. In a multi-frame scene, Track all also starts forward tracking within the new objects' ranges, even if the Auto-Tracking switch is off.
A linked camera box is optional. When one exists for the selected cuboid on the chosen search camera, Find Similar uses that box as its image reference. Otherwise, it derives the image reference from the cuboid and supporting points. If no camera that sees the object has an image on this frame, move to another suitable frame.
Track a cuboid through a sequence
Select a cuboid on a clear frame and check its visibility range on the timeline.
Press T to track forward, R to track backward, or Y to track in both directions within that range. The timeline object's Auto track menu offers Track forward, Track backward, and Track full annotation.
Review the generated keyframes and correct drift, occlusion errors, and incorrect object extent. Use Stop tracking in the timeline object's menu to stop an active or queued run.
To start forward tracking automatically when you draw a cuboid or extend its range forward, open Tracking in the timeline header and enable Auto-Tracking. This requires calibrated cameras with matching images. The setting does not replace checking each track's start and end frames.
Choose interpolation before creating objects
Open Tracking in the timeline header and set Interpolation before creating a track. With it enabled, supported geometry blends between keyframes. With it disabled, the earlier keyframe's geometry is held until the next keyframe. Changing this switch affects newly created tracks; it does not change existing tracks.
Point segmentation does not interpolate point-label arrays between frames. For 3D points, polylines, and polygons, interpolation requires matching vertex counts and order between keyframes. Review intermediate geometry, especially through turns, occlusion, and changes in shape.
Review and correct a cuboid in Batch View
Select a cuboid in a scene with at least two frames, then press B.
Compare its top view across the grid. Each tile shows the frame's point cloud, the cuboid, and its contained point count. A Keyframe badge marks a frame set by hand.
Use Earlier and Later to inspect more frames. Click a tile's Frame button to move the playhead to that frame.
Edit the cuboid directly in a tile to create a correction on that frame.
Press B or Esc, or click Close, to leave Batch View. Then use the perspective, side, and rear views to check height and details that a top view cannot resolve.
New cuboids keep one size across their track. Resizing one on any frame updates its size on the other keyframes too. After a size correction, inspect the rest of the track as well as the edited tile.
Timeline and dynamic properties
The timeline keeps object tracks, geometry keyframes, visibility ranges, and frame-varying properties together. Use it to inspect the first and last valid frame, gaps, reappearances, and state transitions. Keep object properties attached to the correct object and use Item Properties for facts about the scene as a whole.
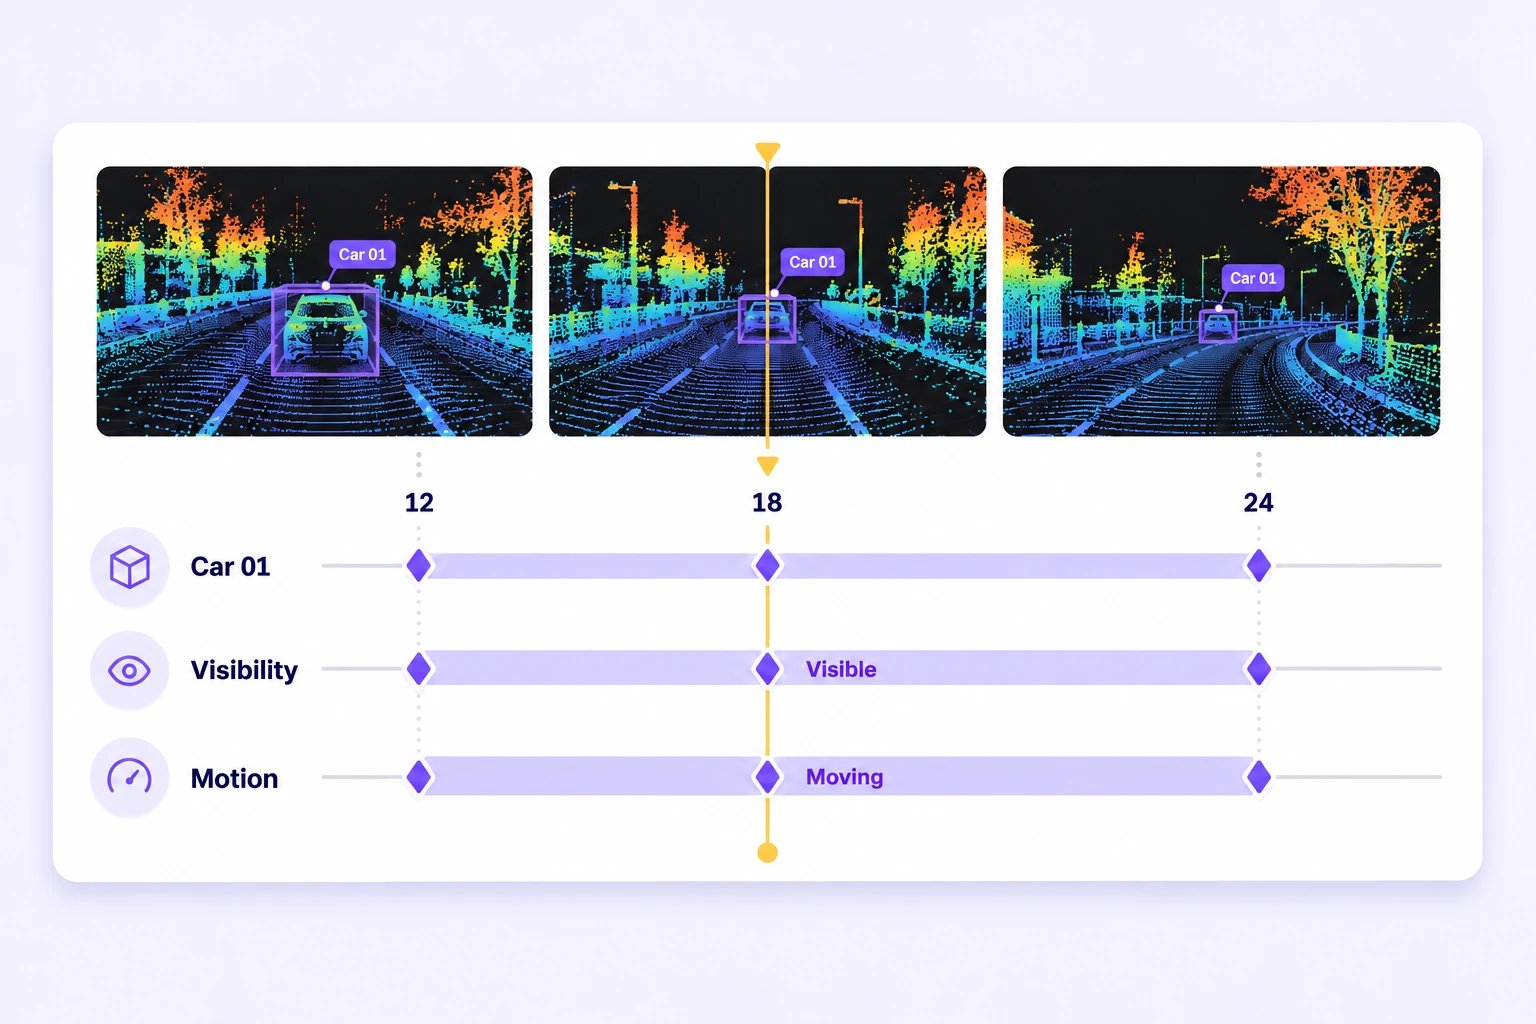
Geometry, visibility, and property intervals should describe the same object at the same frame.
See Properties, relations, and Item Properties for ontology configuration and Validation and conditional logic for required values and dependent fields.
LiDAR keyboard shortcuts
Press H in the active LiDAR editor to open the shortcut dialog. Ctrl/Cmd means Ctrl on Windows/Linux or Cmd on macOS; Alt means Option on macOS. These keys depend on the active tool and selection. Use Space to play/pause and ← / → to change frames.
V
Pan/select mode
N / O / P / L / U
Cuboid / Sphere / Polygon / Polyline / Keypoint
M / E
Paint points / Erase point labels
C
Comment on a location in the scene
[ / ]
Decrease / increase brush size
K / X
Protect existing point labels / Overwrite labels
W / S
Move the selected cuboid forward / backward along its own length
A / D
Move the selected cuboid left / right along its own width
Shift + W / S
Raise / lower the cuboid
Alt + W / S
Make the cuboid longer / shorter
Alt + D / A
Make the cuboid wider / narrower
Alt + Shift + W / S
Make the cuboid taller / shorter while keeping its bottom in place
F / G
Turn the cuboid left / right by 1°; add Shift for 15°
Q
Fit the selected cuboid to the points inside it
B
Toggle Batch View for a selected cuboid in a multi-frame scene
T / R / Y
Track the cuboid forward / backward / both directions
Ctrl/Cmd + A
Select all objects on the current frame in Pan mode
Cuboid moves and size changes use 0.05 m steps. Hold a key to repeat the adjustment; releasing it commits the edit as one undo step. These box keys follow keyboard positions.
In Pan mode, drag empty space with the left button to orbit and the right button to pan. While a drawing or painting tool is active, the right button orbits. Drag an object to move it, or use Alt + drag to move it vertically. Use Ctrl/Cmd + click to toggle an object in a group, or Ctrl/Cmd + drag to select a group; add Shift to extend it.
Click successive points for a polyline or polygon. Finish with a double-click, Enter, or Esc; a polygon can also close on its first point. Backspace/Delete removes the last point while drawing. Between gestures, Esc saves pending painted labels and releases the selection. During a drag or brush stroke, Esc cancels that gesture. In Batch View, Esc closes the view.
See the full Workbench shortcut reference for undo, redo, clipboard, timeline, and other modality controls.
LiDAR annotation quality assurance
Review the 3D evidence before accepting an annotation. Camera alignment is useful evidence, but it does not replace checking the point cloud, dimensions, and temporal behavior.
Data and calibration
The intended sensors, coordinate units, poses, frame ordering, and image pairing.
3D geometry
Cuboid center, dimensions, heading, ground contact, and separation from neighboring objects.
Point segmentation
Complete target coverage, clean boundaries, correct class, and separate instance identity.
Track identity
One real object per track, without switches or accidental merges.
Time and visibility
Valid start and end frames, gaps, reappearances, keyframes, and property intervals.
Ontology and issues
Required values, conditional properties, and correction of unresolved findings.
Use Consensus to compare independent submissions, Quality Gate to compare with approved hidden references, and Review Stages for accountable human decisions. Inspect disagreement in the original 3D scene and relevant frame. Configure explicit destinations for failed or unavailable comparisons; Not evaluated is not a pass.
Consensus supports a LiDAR scene as an individual work item. Data Groups containing LiDAR are not currently supported by Consensus. Comparisons use 3D volume overlap for cuboids and spheres, spatial closeness for points, and path similarity for polylines and polygon boundaries. Polygon comparison measures the boundary, not the filled surface. Painted point segments are compared using their per-point label arrays.
Unreadable label arrays or incompatible point-cloud data cannot establish agreement and require investigation. In Consensus review, painted point labels begin with one selected submission. Other submissions contribute to the comparison, but their painted labels are not automatically fused. Review and correct segmentation disagreements before approval.
Follow QA Overview and QA Workflows to build the process. Calibrate it on representative scenes with the annotation types you intend to produce. Agreement or a benchmark score alone does not establish that every point, track, or calibration field is correct.
Export reviewed LiDAR annotations
Choose UUEF (Unitlab Unified Export Format) to export LiDAR annotations. UUEF preserves 3D shapes and tracks, camera bounding boxes, class properties and point-segmentation labels. It includes the scene's sensor and frame information, with calibration and poses when those were supplied. Track annotations are materialized across their visible frames, with keyframes identified.
Point segmentation includes the segment labels and a separate label array for each annotated frame and sensor. Keep those arrays with the exported JSON so the labels remain associated with their points.
For a release that combines LiDAR with other data families, choose UUEF or Standard Bundle. Standard Bundle uses UUEF for the LiDAR portion. PCD, PLY and BIN are source point-cloud formats; they are not annotation export choices. Direct KITTI or nuScenes annotation export is not available.
The UUEF archive contains annotations and segmentation arrays, while original point-cloud and camera files are downloaded separately. When creating a release, Include export token URL adds persistent source links to supported exports. For scenes uploaded as folders, the UUEF source information links to the complete file listing; its main source link alone represents only the entry file. Download the full scene when you need to preserve its original files, using the source links or SDK/CLI.
Create a small release first and compare it with the Workbench before exporting the full dataset. See Export formats and source inclusion and Inspect, download, and validate.
Next steps
Check the full supported upload formats before preparing other modalities.
Use Video Annotation for frame-based camera labeling and Multimodal overview for grouped cross-modal work.
Curate representative and difficult scenes with Data curation, then freeze membership in dataset versions.
Connect model inference to human correction using Model stages.